Thursday, May 8, 2014

Spring boot is pretty cool

In the not too distant past I sold the powers that be at my workplace on my building an API layer for some of our databases in order to make future projects easier. That of course led to doing research on what I was to use to build such a thing. I ended up playing with a few different tools and landed on Spring Boot as a favorite. Admittedly one of the reasons I gave it a shot was due to my dislike of having to edit XML configuration files. But once I started working with it I found it to be perfect for the type of system I wanted to build. It took care of a crap ton of boilerplate and configuration and then stood back to watch me code in the business logic and ended up being perfect for the Microservices Architecture I wanted to roll out.

So I've given out some pretty hefty praise thus far, but I suppose you're wondering specifically how I came to these conclusions. One of the best demonstrations of this is to look at a simple method from one of my controllers I've got setup.


There are a couple of things to notice in the Git Gist above including a number of interesting annotations that help make everything rather easy. The first of these you'll notice is that @Autowired annotation above my DataSource object. The use of that allows the application to take the configuration I have setup in my application.properties file and then automatically configure the datasource with those settings in mind. That configuration file is incredibly easy to set up as it just looks like this:

spring.datasource.driverClassName=net.sourceforge.jtds.jdbc.Driver
spring.datasource.url=jdbc:jtds:sqlserver://server/database
spring.datasource.username=username
spring.datasource.password=password

The @RequestMapping, @ResponseBody, and @RequestParam annotations are pretty self explanatory which then leaves the JdbcTemplate object. Since ultimately most of the functionality of a web service like this is to simply push data around where it needs to go, being able to call store procedures in a way that isn't super verbose is certainly a win. In the case above we're sending an email and password parameter over to the database and getting back data about a 'consumer.' The consumer is then built into an object through the use of a RowMapper and then returned. Were we attempting to select a bunch of customers this method wouldn't change at all, save for returning a whole List<Consumer> object instead of a single Consumer.

Lastly on this ramble I want to touch on how neat this is for microservices. For example in the application I'm building there are a couple of different databases I wish to push data back and forth from, and those databases have very different purposes. I could build one monolithic application to handle all of it, or I could take a more incremental approach and build each logical piece together as separate services (which is what I decided to do). Spring boot makes this easy to implement because you can export jar files that have an embedded tomcat instance built into them. This allows you to take that jar file on to more or less the server of your choice (with java installed of course) and just kick off the jar. When you need to redeploy something you merely need to stop the jar, replace it and kick it off again. As you can imagine it would be quite easy to automate this via script or your favored management tool. You also gain a bit of resilience with this model as one service need not affect the others if it goes down, be it for maintenance or some sort of catastrophic event. Instead of losing everything you lose functionality for one logical business interest. I could ramble on Microservices for another few paragraphs but instead of punishing you with that I offer you an excellent article on the subject.

That concludes my gushing about Spring Boot. Granted my exposure and use of it is pretty cursory but the experience has been positive thus far. Feel free to comment or email me if you have any questions or opinions to share. Happy coding!

Saturday, January 18, 2014

Glass Sommelier Part 2

Hello again guys, I come bearing a slight bit of news on my first Glass project. I've finished version 0.1 of Glass Sommelier and while it's rather basic it has taught me a bit about how native Glass development works. Right now the application has the following functionality:

  1. Search for wines (made a bit more intelligent with your location built in)
  2. Add a maximum price to your search by using the phrase 'under (number) dollars'
  3. Return a list of wines descending in rating
  4. Save wines to your timeline


Eventually I want to integrate some other ways to save and share the wine you wish to enjoy. For now though I figure it's time to release the bare bones version and let people play with it. If you are a fellow Glass Explorer and would like to play with my app you can get the APK here.  Feel free to ping me if you have any thoughts, questions, or really anything else. Be gentle though as like I said this is my first little experiment screwing around.


I'm hoping to start working on another fun project soon. Once I get a bit further in my coding for that I'll share some details. For now, here are some Glass Sommelier vignettes.


Tuesday, December 17, 2013

Glass Sommelier Part 1

Today I'm posting to let you guys know about a small project I'm working on that I'm rather excited about. The application is called Glass Sommelier and is a piece of Google Glassware that will allow the user to search for wine. The app can be launched by using the touch interface or by saying "Ok Glass, find wine." Once the user has completed a voice search they are then able to use the touch interface to scroll through the results. At that point the user is able to select a wine and then make use of a number of sharing methods in order to save the wine information. I haven't decided exactly which methods will be available at the start though one of them will be to email it to yourself.

For the longer term I'm working on a sort of Wine concierge which involves a bit of secret sauce. The goal of this portion of the application is to find just the right sort of wine based of off a series of questions posed by the Glass device upon your request. This particular portion of the application is probably still a month or two off, but I will definitely post when it's complete.

Once the app is functional and stable enough I'll post an APK so that my fellow Glass explorers can side load it. In the mean time here are teaser screen caps I took using it sitting at my home workstation. Enjoy!


Tuesday, November 12, 2013

Google Glass first impressions

So today ended up being a rather interesting day. I managed to get an invite to the Google Glass Explorer program thanks a friend and I spent the day getting to know the device. In fact I would imagine that this is the beginning of what will be a series of posts talking about Glass, and hopefully a few of them will be about some APKs I'm going to attempt to build and side load into it. So what are my first impressions?

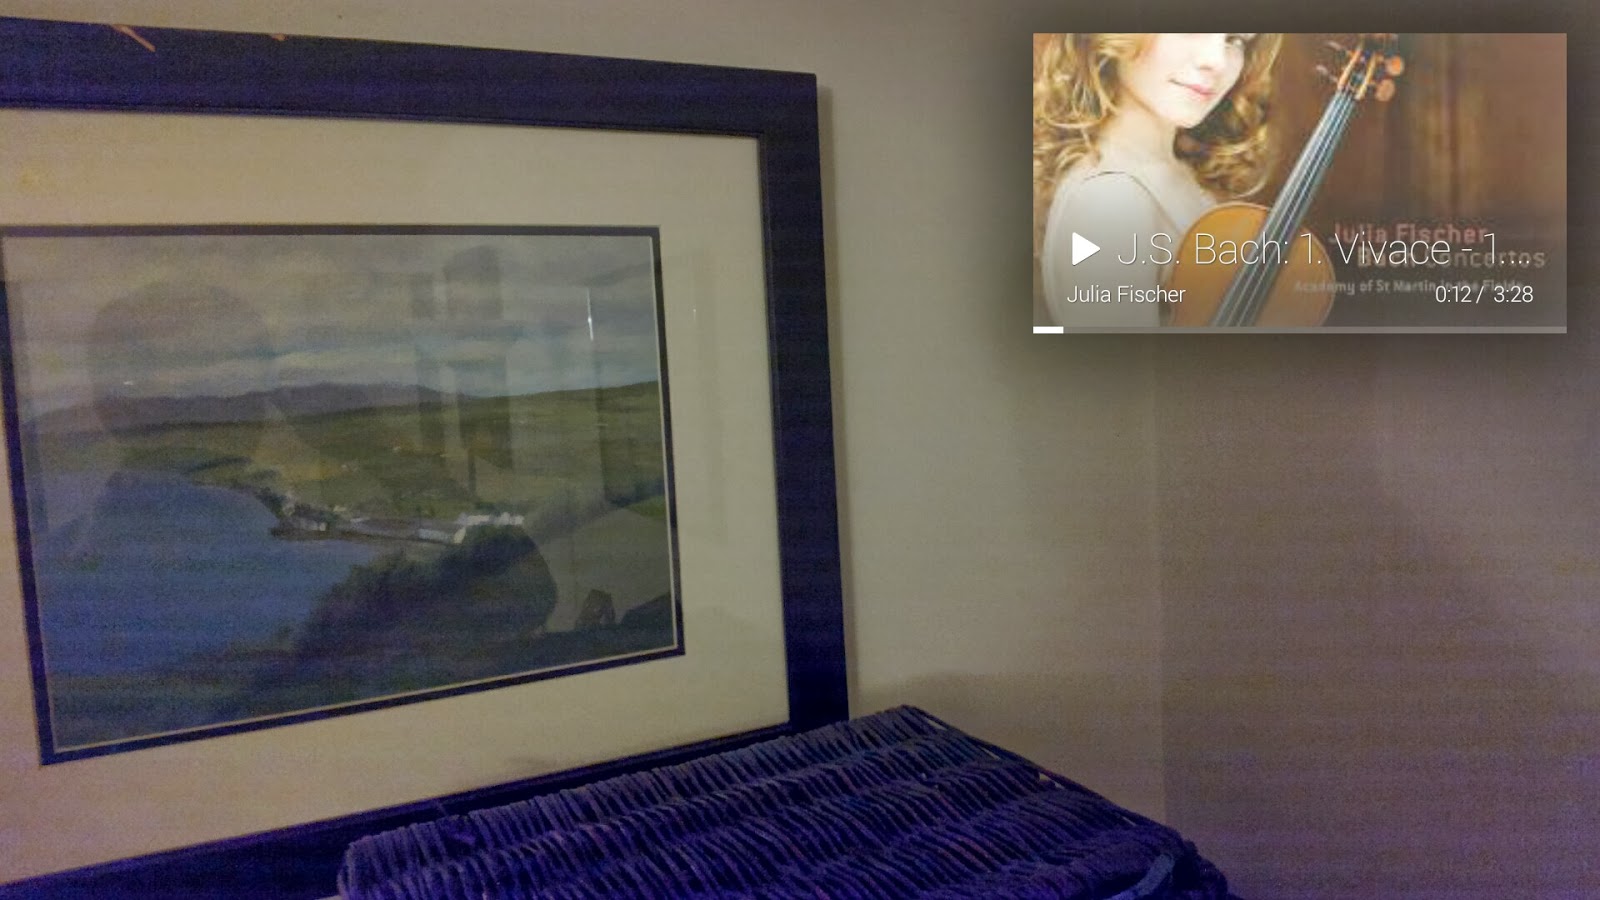
It's exciting. Walking through this thing is like entering a new world. The gesturing between tiles, the use of the interface feels normal, but it's one of those things where you are keenly aware that you are doing something that is vastly different than the norm. After that feeling fades one starts to attempt to get used to what they should and shouldn't use it for. Through out the day today I answered a couple of phone calls with Glass, read the gist of a few emails, and shared a couple of photos. I haven't yet attempted a video call with it yet, but that is certainly on my to do list. I have to say I'm pleasantly surprised thus far with the audio quality on the bone vibration tech, but I will certainly also mess around with the ear bud a little later. Below I've put an image I took with the camera, and a viginette I took to show the music APK in action:


As you can see the camera isn't too bad. It does get a little grainy in lower light scenarios, like the on the second photo there. But thus far I'm happy enough with it. I'll have to take a collection of shots in different conditions to get a true judgement.

As implied I also messed around with the new Music apk. Apparently there is now a Google Music APK floating around that you can load using adb in order to get the streaming service onto glass (instructions can be found here: http://phandroid.com/2013/11/11/google-play-music-google-glass/ and instructions on how to do the adb/debugging part can be found here: http://glassdev.blogspot.com/). I've played around with it a bit and have found the audio quality to be adequate though nothing to write home about. I still need to test with the ear buds however, which I imagine will give improvement.

Lastly, the Google Now integration is perhaps the coolest part. It takes the tiles that you are used to on your Android phone and makes some of that information available to you on glass. Here is an example of what one of those looks like:


There is clearly a lot of exploring I have to do. I'll definitely be writing up some more posts as I get a better impression on the device and/or start building something interesting to play with on it.


Thursday, August 15, 2013

Android and Tesseract (Part 2)

Since we have an environment with the Tesseract Library loaded we can now attempt to write some code utilizing it. I managed to create a simple sample app that can capture an image and then spit out what the text that the OCR managed to pick up. So let's walk through what you'll need for this.

Classes:

I used a series of four classes, including MainActivity:
1. MainActivity.java - The main activity
2. ExternalStorage.java - Operations for saving the image we'll be using
3. OCRActivity.java - Activity in which we interact with the image and OCR
4. OCROperation.java - Backend call to the OCR library

So let's start by looking at the code for MainActivity.java

package com.rkts.tipassistant;

import java.io.File;

import android.app.Activity;
import android.content.Context;
import android.content.Intent;
import android.graphics.Bitmap;
import android.graphics.BitmapFactory;
import android.net.Uri;
import android.os.Bundle;
import android.provider.MediaStore;
import android.util.Log;
import android.view.LayoutInflater;
import android.view.Menu;
import android.view.View;
import android.view.ViewGroup.LayoutParams;
import android.widget.Button;
import android.widget.ImageView;
import android.widget.PopupWindow;
import android.widget.TextView;

public class MainActivity extends Activity {

public static Context appContext;
protected Button _button;
protected ImageView _image;
protected TextView _field;
protected String _path;
protected boolean _taken;
String testURI;

protected static final String PHOTO_TAKEN = "photo_taken";


Bitmap globalBitmap;

@Override
protected void onCreate(Bundle savedInstanceState) {
super.onCreate(savedInstanceState);
setContentView(R.layout.activity_main);
appContext = getApplicationContext();

ExternalStorage.createImageStore();

_image = ( ImageView ) findViewById( R.id.image );
_field = ( TextView ) findViewById( R.id.field );
_button = ( Button ) findViewById( R.id.button );
_button.setOnClickListener( new ButtonClickHandler() );
ExternalStorage es = new ExternalStorage();
_path = es.getImageStore().toString() + File.separator + "receipt.jpg";

File existingReceipt = new File(_path);

if (existingReceipt.exists()) {
boolean deleteSuccess = es.deleteExistingReceipt(existingReceipt);
if (deleteSuccess == true) {
Log.d("Debug(MainActivity): ","Removed existing image");
}
else Log.d("Debug(MainActivity): ","No existing image to remove");
}


}

@Override
public boolean onCreateOptionsMenu(Menu menu) {
// Inflate the menu; this adds items to the action bar if it is present.
getMenuInflater().inflate(R.menu.activity_main, menu);
return true;
}

@Override
protected void onSaveInstanceState( Bundle outState ) {
outState.putBoolean( MainActivity.PHOTO_TAKEN, _taken );
}
@Override
protected void onRestoreInstanceState( Bundle savedInstanceState)
{
Log.i( "MakeMachine", "onRestoreInstanceState()");
System.out.println(savedInstanceState.getBoolean(MainActivity.PHOTO_TAKEN));

if( savedInstanceState.getBoolean( MainActivity.PHOTO_TAKEN ) ) {
onPhotoTaken();
}
}


public class ButtonClickHandler implements View.OnClickListener
{
public void onClick( View view ){
startCameraActivity();
}
}

protected void startCameraActivity()
{
File file = new File( _path );
Uri outputFileUri = Uri.fromFile( file );
System.out.println(Uri.fromFile(file));
testURI = Uri.fromFile(file).toString();
Intent intent = new Intent(android.provider.MediaStore.ACTION_IMAGE_CAPTURE );
intent.putExtra( MediaStore.EXTRA_OUTPUT, outputFileUri );

startActivityForResult( intent, 0 );
}

@Override
protected void onActivityResult(int requestCode, int resultCode, Intent data)
{
Log.i( "MakeMachine", "resultCode: " + resultCode );
switch( resultCode )
{
case 0:
Log.i( "MakeMachine", "User cancelled" );
break;

case -1:
onPhotoTaken();
break;
}
}


protected void onPhotoTaken()
{
_taken = true;
beginOCROp();
Log.d("Debug(MainActivity.onPhotoTaken:","End of method");
}


public void beginOCROp() {

Intent intent = new Intent();
intent.setClass(this, OCRActivity.class);
startActivity(intent);

}
}


What you'll see here is that during the onCreate() we set our selves up properly to write to device storage by using the getImageStore method. If my memory serves this should work for both devices with separated internal storage and those with actual external removable storage. We also set up our basic buttons, set a context for us to reference in other classes, and set our onClickListeners for our simple UI buttons. Down as we go you'll see the ButtonClickHandler which simply makes a call to the startCameraActivity method. That method is used to prep our use of the camera to store our image file that we will then analyze with the OCR library. One thing that is important about the startCameraActivity is the intent that comes back to it. In order to handle that intent data we have the onPhotoTaken() method which has a switch that determines what our course of action is. Essentially if we actually take a photo it kicks off beginOCROp() which starts the OCRActivity activity and if the user cancels it takes us back to our original state.

Now let's take a look at ExternalStorage.java

/**
*
*/
package com.rkts.tipassistant;

import java.io.File;
import java.io.FileOutputStream;
import java.io.IOException;
import java.io.InputStream;
import java.io.OutputStream;

import android.content.Context;
import android.content.res.AssetManager;
import android.os.Environment;
import android.util.Log;

/**
* @author ryan
* This class is for operations that affect the device external storage.
*/
public class ExternalStorage {
String _path;
static File imageStoreDirectory;

public ExternalStorage() {

}

public ExternalStorage(File receipt) {

}

//This method is used to create the initial image store folder on external storage if it does not exist and is not a directory.
public static void createImageStore() {

File externalStorage = Environment.getExternalStorageDirectory();
imageStoreDirectory = new File(externalStorage + File.separator + "tipAssistant");

System.out.println("ImageStoreDirectory Exists?:" + imageStoreDirectory.exists());

Log.d("Debug:","Directory logic check");

if (imageStoreDirectory.exists()==false && imageStoreDirectory.isDirectory()==false) {
imageStoreDirectory.mkdir();


}
ExternalStorage es = new ExternalStorage();
es.copyAssets();

}

public Boolean deleteExistingReceipt(File receipt) {
boolean success = receipt.delete();
return success;

}

public File getImageStore() {
return imageStoreDirectory;
}


private void copyAssets() {
Context context = MainActivity.appContext;
_path = getImageStore().toString() + File.separator + "tessdata";
File tessdata = new File(_path);
if(!tessdata.exists()) {
tessdata.mkdir();
Log.d("Debug(ExternalStorage(copyAssets):","Making tessdata dir");
}

_path = getImageStore().toString() + File.separator + "tessdata";
AssetManager assetManager = context.getAssets();
String[] files = null;
try {
files = assetManager.list("");
System.out.println(files[0]);
} catch (IOException e) {
Log.e("tag", "Failed to get asset file list.", e);
}
for(String filename : files) {
InputStream in = null;
OutputStream out = null;
try {
in = assetManager.open(filename);
out = new FileOutputStream(_path + File.separator + filename);
copyFile(in, out);
in.close();
in = null;
out.flush();
out.close();
out = null;
} catch(IOException e) {
Log.e("tag", "Failed to copy asset file: " + filename, e);
}
}
}
private void copyFile(InputStream in, OutputStream out) throws IOException {
byte[] buffer = new byte[1024];
int read;
while((read = in.read(buffer)) != -1){
out.write(buffer, 0, read);
}
}


}

This class will handle our I/O operations with storage on the device in question. In our case all we are really looking to do is to create the folder we wish to store the image in temporarily, make sure our tesseract required files are in the proper place, and of course save (or delete and save if something is there) an image for us to analyze. createImageStore() handles prepping the storage environment for our use. It simply checks if the appropriate folder structure exists, and creates it if it does not. We have a method to delete the existing image file and return the success or failure of the operation (deleteExistingReceipt()) as well as a method to get the path to the image store (getImageStore()). After that is what we use to make sure tesseract will behave. We use the copyAssets() method to copy over all the resource data that tesseract needs on the device in order to operate properly. Lastly we have copyFile which is pretty self explanatory and just uses a buffer object.

Next we have OCRActivity.java


package com.rkts.tipassistant;

import java.io.File;

import android.os.Bundle;
import android.os.Environment;
import android.app.Activity;
import android.graphics.Bitmap;
import android.graphics.BitmapFactory;
import android.view.Menu;
import android.view.MenuItem;
import android.widget.ImageView;
import android.support.v4.app.NavUtils;

public class OCRActivity extends Activity {

@Override
protected void onCreate(Bundle savedInstanceState) {
super.onCreate(savedInstanceState);
setContentView(R.layout.activity_ocr);
// Show the Up button in the action bar.
//getActionBar().setDisplayHomeAsUpEnabled(true);
String _path;
ExternalStorage es = new ExternalStorage();
_path = es.getImageStore().toString() + File.separator + "receipt.jpg";

File receiptImg = new File(_path );
System.out.println(_path);


try {
System.out.println("setting imageview to receipt...");
ImageView receipt = (ImageView) findViewById(R.id.previewReceipt);
BitmapFactory.Options options = new BitmapFactory.Options();
options.inSampleSize = 4;
Bitmap myBitmap = BitmapFactory.decodeFile(_path, options);
receipt.setImageBitmap(myBitmap);
}
catch (Exception e) {
e.printStackTrace();
}

try {

OCROperation ocr = new OCROperation(_path);
ocr.runOCR(_path);

}
catch(Exception e) {
e.printStackTrace();
}


}

@Override
public boolean onCreateOptionsMenu(Menu menu) {
// Inflate the menu; this adds items to the action bar if it is present.
getMenuInflater().inflate(R.menu.activity_ocr, menu);
return true;
}

@Override
public boolean onOptionsItemSelected(MenuItem item) {
switch (item.getItemId()) {
case android.R.id.home:
// This ID represents the Home or Up button. In the case of this
// activity, the Up button is shown. Use NavUtils to allow users
// to navigate up one level in the application structure. For
// more details, see the Navigation pattern on Android Design:
//
// http://developer.android.com/design/patterns/navigation.html#up-vs-back
//
NavUtils.navigateUpFromSameTask(this);
return true;
}
return super.onOptionsItemSelected(item);
}

}


This one is pretty straight forward. The activity onCreate attempts to retrieve the image we have created, decode it, and then run the runOCR method from the OCROperation class. The activity also puts the image in an image view so you can see what you are working with when the text comes out the other side (to check for correctness).

Lastly we have OCROperation.java. This is perhaps the meat and potatoes of what we are trying to do here.


/**
*
*/
package com.rkts.tipassistant;

import java.io.File;
import java.io.IOException;

import android.graphics.Bitmap;
import android.graphics.BitmapFactory;
import android.graphics.Matrix;
import android.media.ExifInterface;
import android.os.Environment;

import com.googlecode.tesseract.android.TessBaseAPI;


/**
* @author ryan
*
*/
public class OCROperation {

ExternalStorage es = new ExternalStorage();

public OCROperation(String _path) {

}

public void runOCR(String _path) throws IOException {
// _path = path to the image to be OCRed

BitmapFactory.Options options = new BitmapFactory.Options();
options.inSampleSize = 4;

Bitmap bitmap = BitmapFactory.decodeFile(_path, options);


ExifInterface exif = new ExifInterface(_path);
int exifOrientation = exif.getAttributeInt(
ExifInterface.TAG_ORIENTATION,
ExifInterface.ORIENTATION_NORMAL);

int rotate = 0;

switch (exifOrientation) {
case ExifInterface.ORIENTATION_ROTATE_90:
rotate = 90;
break;
case ExifInterface.ORIENTATION_ROTATE_180:
rotate = 180;
break;
case ExifInterface.ORIENTATION_ROTATE_270:
rotate = 270;
break;
}

if (rotate != 0) {
int w = bitmap.getWidth();
int h = bitmap.getHeight();

// Setting pre rotate
Matrix mtx = new Matrix();
mtx.preRotate(rotate);

// Rotating Bitmap & convert to ARGB_8888, required by tess
bitmap = Bitmap.createBitmap(bitmap, 0, 0, w, h, mtx, false);
bitmap = bitmap.copy(Bitmap.Config.ARGB_8888, true);
}

TessBaseAPI baseApi = new TessBaseAPI();
// DATA_PATH = Path to the storage
// lang for which the language data exists, usually "eng"
File externalStorage = Environment.getExternalStorageDirectory();
File baseDir = new File(externalStorage + File.separator + "tipAssistant");
String path = baseDir.toString() + File.separator;
baseApi.init(path, "eng"); baseApi.setImage(bitmap);
String recognizedText = baseApi.getUTF8Text();
baseApi.end();
System.out.println(recognizedText);


}


}


Here we are taking the image stored on the device and prepping it for use with the OCR library. To do this we make use of ExifInterface and the bitmap object. In tandem these make sure that we have the appropriate data type to analyze and that the user rotating the device wont screw us up too badly. At the end we actually create the TessBaseAPI object that is then instantiated and used to pull a string out of the image. Interestingly enough the actual call that gets you the string is quite simple:


String recognizedText = baseApi.getUTF8Text();

Once you set that string value you can take the information and do anything you'd like with it. The only thing limiting you at that point is your ability to manipulate strings.


I hope this was some what informative as I did have a bit of fun playing around with the library in order to write this. Feel free to comment or shoot me an email if you have questions or concerns.


Friday, June 21, 2013

Android and Tesseract (Part 1)

Over the past few days I've been playing around with the Tesseract native packages that one can rope into a library for Android applications. This library allows one to conduct optical character recognition on Android mobile devices, which is a rather intriguing concept. The ability to do this has been around for some time (2006). You can read more general information on its history and where it comes from here: http://en.wikipedia.org/wiki/Tesseract_(software). The story is rather interesting as the software was originally written by Hewlett Packard in the late 80s early 90s area and sometime down the road ended up in the possession of Google and thereafter available for use in Android. So I figured I'd share a bit on my experience with it in two parts. The first of these will be a brief overview on the setup and the next part will be a bit with some sample code I managed to get together for its use.

The set up is a fairly easy task, though it does require a little bit of critical thinking as there are some problems that can be hard to work through even with community resources. Before you start a project of your own, make sure your IDE (in my case Eclipse) has the ability to compile Java and C++. If you need to add this feature on Eclipse you can find it in their Indigo repository by adding it through the Help > Install New Software dialog.


Once you have those things you'll need to go out and download the Tesseract library project files which you can find here: https://github.com/rmtheis/tess-two. You can either clone the repository or simply download an archive copy, the choice is yours on that front. Upon download you then can simply import this project into your IDE environment. When you've finished doing so you'll want to make sure you have checked off in your project properties that it is indeed an Android library. In Eclipse it looks like the below screenshot.


After that you will need to make sure you have set up the Java NDK (http://developer.android.com/tools/sdk/ndk/index.html) with the TessTwo project . All you have to do here is unpack the archive somewhere accessible and define the path to it in your IDE. In my Eclipse set up the setting is here under the project properties:


Then you just need to run a build on it and let the IDE do its work. The build can take some time so if I were you I'd suggest finding something to do while the time passes. After the build completes you are ready to use it in a project. We will go into actually making use of this on the next post which I hope to have hammered out here this coming week.


Tuesday, May 21, 2013

Apologies and some news

First off I must apologize for neglecting this blog for a while. Over the past couple of months I have been going through a bit of a professional transition that has left me rather occupied and distracted. I will however make the effort to begin posting weekly once more and perhaps more often should time permit.

On to the second agenda item is a bit of news. As one may have found out from either linkedIn or a response to a blog comment I left a couple days ago, I am no longer working at Trustyd. It is a sad and unfortunate turn of events that lead to this point, but I have been away from that particular organization since sometime in April. If you see this and do have any questions for me about this, or wish for advice as someone who has a deep knowledge of the product, feel free to contact me via email (koch.ryan@gmail.com).

In any event I hope to return to the regular scheduled posting here within the next day or so. I will try to think of a riveting topic for all of you to enjoy!

Tuesday, February 12, 2013

Hard drives and Pacific disputes

Now reading the title of this you might wonder what Hard drives and territorial disputes in the Pacific ocean could possibly have to do with one another. As you may be privy to we experienced a hard drive shortage due to some natural disasters in 2011 and the reverberations of this can still be felt in prices today to some degree. One thing to note in all of this is that a fair share of the companies with production in Thailand and other places are owned by Japanese companies. With tensions rising between Japan and China over a set of disputed islands one might wonder if a potential conflict could exacerbate the shortage and drive prices up again.

The dispute is over small islands in the East Asian sea known as Diaoyu in China and the Senkaku in Japan. Some what recently there have been semi severe incidents in which a provocation was a real risk. An example of this recently is a Chinese vessel locking radar onto a Japanese warship. The Pacific is full of such disputes especially considering the nine dotted line map China released showing the territory they see as rightfully theirs.

But what does this have to do with hard drive supplies? Well an overlooked problem is one we faced previously as a bottle neck and that is the motor. Japan's Nidec firm which produces around 80% of the motors has some portion of its manufacturing based in China. Any conflict may reduce the production capacity of this operation and thus limit the number of hard drives available. A possible conflict could create other problems as computer components are manufactured all over East and South East Asia and a conflict between China and one of those parties may bring to bear significant barriers to trade for the duration. At the end of it the cost to trade will ultimately be paid by consumers who would have to pay premiums for technology goods whose supplies are strained.

The next question is how likely is all of this. Personally I believe China and Japan will find that it is not in their best interest to pursue a conflict, and that this is a rather unlikely scenario. It is not in China's best interest to become a belligerent power as it goes against their philosophy of a peaceful rise, which they have been using the assuage the concerns of regional powers. Japan would suffer in losing market access to China and the loss in manufacturing for companies with plants based there. Ultimately it doesn't look like it would be a positive for either power, however pride and territorial disputes can make nations act rather irrationally.

Thursday, January 17, 2013

Wing it and start coding

One of the better professional experiences I've had of late is attempting to learn how the Android environment works in regards to developing for it. I was tasked with a project involving the creation of an application which really had a very simple goal. But the task seemed horribly daunting, while I had taken object oriented programming, and have messed around with a few languages in the past I had not tried to develop anything for mobile. Honestly I have found the best thing to do is just jump in and start.

Seriously, just start planning the project

As with a lot of things the first step is the hardest. I spent a long time reading through random portions of the Android API documentation (http://developer.android.com/develop/index.html). Eventually though one has to actually start designing their project and then coding it. So one day I just started jotting down that the thing was supposed to do on a white board. After writing out each individual task the application needed to achieve, it was then easy to break it down into individual methods and classes. After that you now have a path or a check list of all the things you need to learn how to do in java using the Android APIs.

For example I needed to write an app to interpret XML data, store it and then display it to the user on demand, and complete the parse/download on a background thread. So breaking it down the tasks are:

- Download XML data and parse it
- Create storage space for parsed result
- Create some sort of UI to view results stored in a Database
- Start the download/parse on some sort of regular schedule

Those 4 tasks can then be broken up into individual methods and classes. For example in using a database to store information I needed to write a Database Handler to create it, define it's schema, and define all the I/O methods (more or less the CRUD stuff). One thing that is interesting to read is Oracle's beginning guide to java which also covers object oriented thinking as it's that sort of language (link: http://docs.oracle.com/javase/tutorial/java/concepts/).

Start using Google to find tutorials for everything

In my experience with this I found that more or less everything I was trying to do had been done by someone else in the past in some form, and was documented. It's actually really easy to search for and then figure out how to write classes and methods for a whole variety of tasks. For example I needed to figure out how to parse XML and found an amazing tutorial on that portion and combined with the lessons learned from a tutorial on Sqlite (embedded database).

Outside of doing stuff with Android I've also found that Code Academy is a pretty cool place to learn about coding. The interactive projects are actually rather good and certainly do an excellent job of teaching one the way a language works. It's perfect for beginners or someone trying to pick up a new language for kicks. Here's a link: www.codeacademy.com

I suppose while this article seems a bit aimless the point is to share with you that coding is fun and easy to pick up if you look in the right places. The internet is filled with pretty much everything you need from API docs, SDK docs, and tutorials. The best part is most of is completely free. So go ahead and wing it and start coding!

Wednesday, December 19, 2012

Linux server performance

In my daily tasks I deal with a lot of Linux servers, and from time to time decide to tweak them for performance reasons, depending on what task they are executing. A lot of the units I'm dealing with tend to be operating a postgres database and some sort of data store for a custom application that is being run (usually via tomcat). I've found that there are three easy things to play around with in order to get the most out of the system, especially if the resources on the box are fairly limited. Those things are the swappiness value, the I/O scheduler, and use of the renice command implemented with a script called via crontab.

Swappiness

The Swappiness value is what systems administrators and engineers use to instruct the linux kernel on how aggressive the system should be in storing pages of memory on disk, as opposed to in memory. Most default installations have this value at 60 which is supposed to represent a balanced number (the range is: 0-100). In my situation where I'm running a lot of database operations I've found that a higher value seems to help free up memory for use in postgres related processes, where otherwise idle system processes may have been holding on to that memory. This has been particularly effective in situations where I have application servers with just barely enough memory to get by.

You can adjust the swappiness value two ways. The first is more of a testing/temporary measure and can be done by using the following command (via the terminal):

sysctl -w vm.swappiness=(value you'd like to set it to)

You can also make this change by editing the following file: /proc/sys/vm/swappiness . One should exercise caution when editing this file though as it does require a bit of monitoring to make sure that you aren't breaking vital processes when changing memory allocation settings.

I/O Scheduler

CFQ (Completely Fair Queuing)
If my memory is still serving me well, on most Linux distributions this is the default setting. This scheduler serves as a sort of general use setting as it has decent performance on a large number of configurations and uses ranging from servers to desktops. This scheduler attempts to balance resources evenly for multiple I/O requests, and across multiple I/O devices. It's great for things like desktops or general purpose servers.

Deadline
This one is particularly interesting as it more or less takes 5 different queues and reorders tasks in order to maximize I/O performance and minimize latency. It attempts to get near real time results with this method. It also attempts to distribute resources in a manner that avoids having a process lose out entirely. This one seems to be great for things like database servers, assuming that the bottle neck in the particular case isn't CPU time.

Noop
This is a particularly lightweight scheduler and attempts to reduce CPU latency by reducing the amount of sorting occurring in the queue. It assumes that the device(s) you are using have a scheduler of their own that is optimizing the order of things.

Anticipatory
This scheduler uses a slight delay on I/O operations in order to sort them in a manner that is most efficient based on the physical location of the data on disk. This tends to work out well for slower disks, and older equipment. The delay can cause a higher level of latency as well.

In choosing your scheduler you have to consider exactly what the system is doing. In my case as I stated before I am administering application/database servers with a fair amount of load, so I've chosen the deadline scheduler. If you'd like to read into these with a bit more detail I'd check out this Redhat article (it's old but still has decent information: http://www.redhat.com/magazine/008jun05/features/schedulers/)

You can change your scheduler either on the fly by using:
echo <scheduler> > /sys/block/<disk>/queue/scheduler

Or in a more permanent manner (survives reboot) by editing the following file:
/boot/grub.conf
You'll need to add 'elevator=<scheduler> to the kernel line.

Using renice

Part of what my boxes do is serve up a web interface for users to interact with. When there are other tasks going on and the load spikes access to this interface can become quite sluggish. In my scenario I'm using tomcat as the webservices application and it launches with a 0 nice value (the normal user priority level in a range from -15-15 with lower being more important). The problem with this is that postgres also operates on the same priority and if it is loaded up with queries they are both on equal footing when fighting for CPU time. So in order to increase the quality of the user experience I've decided to set the priority for the tomcat process to -1, allowing it to take CPU time as needed when users interact with the server. I've done this using a rather crude bash script, and an entry on crontab (using crontab -e).

The script
--

#!/bin/bash
tomcatString="$(ps -eaf|grep tomcat|cut -c10-15)"
renice -1 -P $tomcatString
--
The crontab entry:
--
*/10 * * * * sh /some/path/here/reniceTomcat
--


All the above uses are the ps,grep, and cut commands to pull the process ID and then run the renice command on that ID by streaming it in. The crontab entry just calls it on a periodic basis to make sure the process stays at that priority. In the case of the above it's doing it every 10 minutes, but it can be set to just about any sort of scheduling. To read more on how to use cron scheduling check out this article: http://www.debian-administration.org/articles/56.


Thursday, November 29, 2012

Analytics in Columbus?

I read something rather interesting in the paper this morning. It would seem that IBM is putting a new analytics center right in my backyard here in Columbus Ohio. This is big news for the city as it's supposed to bring in around 500 new tech jobs as well add credibility to the region as a tech center. Data/Business Analytics is a fascinating field, and is certainly worth a gander as it represents something significant for the future of the technology sector.

You see right now all the talk is about 'big data' and how it is stored, where it is served from, how its collected. But the lingering question that a lot of companies are now answering is 'what do you do with it once it's there?'. Companies such as IBM are taking this data boiling it down and using it to formulate strategies, see patterns of behavior that might be uncouth, and where consumer interest is going. This trend has caused a new type of IT job to exist that is an interesting mix of both technological, and business savvy.

What all of this means for those of us here in the Midwest is that its a step toward breaking the assumption that all of the IT talent is on either the east or west coast of the US. So all in all this should be a positive sign for the economy here, plus I must add it will be interesting to see the sort of talent that Ohio State is able to churn out for this field. To that end the Fisher College is opening up a new Graduate program for it, and the college itself is looking into something in the undergrad arena.

There should be some interesting times ahead for the Tech sector in Columbus.

Wednesday, November 14, 2012

Deficit Hawk: A cool federal budget app

So due to my being a bit of a public policy nerd on top of my enjoyment of technology I started playing around with an app on the Google Play Store called 'Deficit Hawk'. A friend of mine had suggested it, and I must say its a neat little app. It takes CBO projections, and possible choices that cover new revenues as well as cuts and allows you to attempt to set a budget plan. It's incredibly easy to use, and gives you a nice graph so you can see how you are doing.

The plan I created when messing around with it is below:


----- NEW SPENDING CUTS -----

$-88.0 billion over ten years - Add a Public Plan to the Health Insurance Exchanges

$-88.5 billion over ten years - Apply the Social Security Benefit Formula to Individual Years of Earnings

$-112.0 billion over ten years - Base Social Security Cost-of-Living Adjustments on an Alternative Measure of Inflation

$-2.0 billion over ten years - Charge transactions fees to fund the Commodity Futures Trading Commission

$-4.8 billion over ten years - Drop Wealthier Communities from the Community Development Block Grant Program

$-20.8 billion over ten years - Increase Fees for Aviation Security

$-26.5 billion over ten years - Increase Guarantee Fees Charged by Fannie Mae and Freddie Mac

$-241.2 billion over ten years - Increase the Basic Premium for Medicare Part B to 35 Percent of the Program's Costs

$-85.6 billion over ten years - Limit Highway Funding to Expected Highway Revenues

$-62.4 billion over ten years - Limit Medical Malpractice Torts

$-84.6 billion over ten years - Link Initial Social Security Benefits to Average Prices Instead of Average Earnings|Implement progressive price indexing

$-124.8 billion over ten years - Raise the Age of Eligibility for Medicare to 67

$-119.9 billion over ten years - Raise the Full Retirement Age in Social Security

$-642.0 billion over ten years - Reduce Growth in Appropriations for Agencies Other Than the Department of Defense|Freeze Funding at 2011 Level

$-610.7 billion over ten years - Reduce the Growth in Appropriations for the Department of Defense|Freeze Funding at 2011 Level

$-112.0 billion over ten years - Require Manufacturers to Pay a Minimum Rebate on Drugs Covered Under Medicare Part D for Low-Income Beneficiaries

$-3.6 billion over ten years - Transfer the Tennessee Valley Authority's Electric Utility Functions and Associated Assets and Liabilities


----- NEW REVENUE -----

$309.5 billion over ten years - Accelerate and Modify the Excise Tax on High-Cost Health Care Coverage

$96.1 billion over ten years - Expand Social Security Coverage to Include Newly Hired State and Local Government Employees

$241.4 billion over ten years - Extend the Period for Depreciating the Cost of Certain Investments

$70.9 billion over ten years - Impose a Fee on Large Financial Institutions

$456.8 billion over ten years - Increase the Maximum Taxable Earnings for the Social Security Payroll Tax

$1.2 trillion over ten years - Limit the Tax Benefit of Itemized Deductions to 15 Percent

$48.7 billion over ten years - Raise Tax Rates on Capital Gains


--------

In any case if you have an interest in public policy, and you enjoy playing around with neat apps on your phone or tablet I suggest giving this a go.

Monday, November 5, 2012

What is data protection really?

Data protection is a vague term that I've seen being thrown about. I've observed it being used in reference to data backup software, security software, network security devices, and well really to all sorts of software and hardware platforms and devices. I've come to the conclusion that data protection is some bit of all of these things and ultimately is about three factors: protection from loss, protection against leak, and the ability to ensure the data can be trusted.

Data loss is perhaps the most fiscally costly, and best known portion of data protection. It is here that you have your nightmare scenarios about all the customer data being gone, and your IT staff is rung up in the middle of the night to rush around to save what they can. These days most are conducting some form of data backup to cover themselves here, and the wiser of us are doing so to off site locations. Obviously this one is something that every organization should have covered at the minimum, though if you aren't sure this is taken care of go ahead and take a look at this post that kicks off a series on backup solutions, and this one which is a webinar about backup solutions.

Data leak is perhaps equally dangerous, though not as often thought about. This area of data protection involves the act of a malicious party gaining access to your sensitive information for some sort of nefarious purpose. A leak can harm not only those of whom the data belongs to or references, but also the reputation of the organization that has been breached.

The risks of leak are present in three stages, transmission, storage, and actions by the internal users themselves. It is important then that all transmitted communications have some form of encryption enabled, be they emails, backups, or other web transactions between customers or internal users. Sending anything across in plain text is just asking for a breach. These days most sites and services provide this, and just about every email service be it hosted or self hosted is capable of some level of protection here. Encryption of stored data is also rather important, and is increasingly so for those with laptops on the road. I can say that I've had my personal information exposed to the world on two occasions due to a laptop being stolen. It's a frustrating circumstance, and can cause all sorts of havoc for a business. It's important to do some for of encryption on your laptops, and its easy with the free solutions out there (like truecrypt).

Trust is important as well. When you are backing something up, or interacting with a web service how can you be assured that you are accessing data that is without malicious content. There are solutions that do this in some sort of piecemeal format be it scanning your computer to make sure it's up to date, or doing general scans to ensure OS integrity, but I'm not aware of a true comprehensive point to point solution. When interacting with questionable web services I might suggest running some sort of sandbox utility, such as that offered by avast, or sandboxie.

Tuesday, October 9, 2012

Why your SMB needs a private cloud

For small to medium size enterprises (SMB) the private cloud is the next natural step for their IT infrastructure. Their employees need access to data no matter where they are, and the employer needs them to be always on, and always connected. The organization is going to want to accomplish this goal in a manner that is cost effective, secure, and able to be owned.

Employees need their data. Almost every job these days from sales to engineering requires access to either some form of CRM (customer relations management) interface, ticketing system, knowledge base, or some other database oriented solution. Setting up some form of private cloud environment that is accessible from anywhere is the key to giving them what they need. It's becoming easier and easier to set up an infrastructure these days as well. You really just need some blade servers and some sort of virtualization platform tossed on top in order to deploy virtual machines to serve your purposes. Ultimately your deployment becomes less about hardware and more about services and software.

Your infrastructure cost should go down over time as well. While you wont be able to layoff your IT team, they will be able to automate more tasks, centralize more of the infrastructure, and spend time on things that develop the business instead of fighting fires. If you set up more centralized infrastructure with a proper disaster recovery and business continuity plan utilizing backup essentials you can create a resilient and accessible set of services for your employees and customers.

Ownership is also an issue of great import. One of the next big things in IT is going to be the 'how' in determining what filters to place on all this data that has been collected on users. The answer to that question is going to bring up a lot of privacy concerns, as well as the issue of user rights v. owner rights. Through the use of a private cloud you can avoid some of those pitfalls that you would run straight into by going to a public provider. The key portion of this is that in a private cloud scenario your data is housed in something you physically own. If you need to pull something, or migrate the data away you can and without being impeded by the governance of another organization outside of your own.

In owning the infrastructure yourself you can also lessen the risk of data leak. You have the opportunity to set your own strict testing and security standards. In the hands of another company your are subject to what ever policies they have dreamt up, be they for better or worse. This sort of thing is especially important if you are storing proprietary data, or personally identifiable customer/employee information.

The move to the private cloud is a natural step forward. We've witnessed over the past twenty years the empowerment of the personal desktop, which lead to the beginnings of a collaborative office environment. Now we're moving to each organization having it's own private cloud of computing power, giving them further capabilities and control. Your organization can move from a collaborative office environment to being that of a collaborative organization. No matter where your employees are, they can communicate and in a manner that is under your control. 

Monday, September 24, 2012

Backup Essentials Part Four

We have now finally arrived to the conclusion of the Backup Essentials series of posts. Part four may be the most important one to consider, as it is the factor that will have the single largest impact on your customers. For our conclusion we'll be covering testing and expectations management, and while these things don't sound as technically exciting as the previous parts they are critical to your business. In covering this topic we'll hit four key areas: Bench marking, availability, retention compliance, and configuration auditing.

Bench mark testing is critical in gathering data for you to use to set reasonable expectations for your customers. Periodic testing of exactly how long your backup solution takes to conduct operations is imperative if you wish to be able to speak credibly to a client about your capabilities. I am always pushing clients at my work to conduct test restores from random client machines at least a couple of times a month in order to keep track of restore time frames. Taking that data and coming up with an average of sorts will allow you to say with some confidence the amount of downtime a client could expect in a disaster. If your clients are attempting to form a service level agreement (SLA) it's especially prudent to have this data available to you.

Just as important is to check the integrity of your data. We gain hark back to conducting test restores, but in this case we have to take a step further than just testing I/O speeds. For example if you are backing up a SQL database the step has to be taken to attempt to do a RESTORE from the dump file (on a dev/test environment). The ideal test gets as close to a real world disaster scenario as possible, and even better if you train your associates to document practices and problems along the way. The data gathered from these tests can form the bedrock of a larger business continuity strategy as you figure out what resources need to go where, and the best placement for your experts. I generally suggest conducting some form of disaster test once every month or two, and at the minimum once every ninety days.

Let us also not forget about retention policies. It is important to double check your backup solution to make sure that any storage retention policies that you have set up are being enforced properly. The last thing you need is to either have your space taken up needlessly (driving up the cost of the solution and decreasing performance), or not have a set of data due to a retention policy that is too tight and unchecked.

Lastly we have configuration auditing. It's useful from time to time to go back through the rules that define what data is being backed up in order to make sure they are still valid. Over time companies move files around, migrate databases and email stores, and well ultimately things are always changing. It would be rather embarrassing to find that one was backing up an empty directory because the backup parameters haven't been checked in months. This is something that should be checked at a weekly or biweekly rate and requires close cooperation with leaders in other parts of the business in order to ensure accuracy.

The conclusion you should draw from this is that testing, auditing and compliance are terribly important. Conducting these properly will allow you to set reasonable expectations with your customers, give you confidence in your technical solutions, and will give your customer reason to have confidence in you.

Thursday, August 23, 2012

Backup Essentials Part Three

It's time for part three of this series. What we're discussing here is what to keep in mind when selecting your backup solution. The factors we'll be discussing include: data availability, administrative cost of the solution, portability, and security.

Data Availability
This factor is always a balance that has to be struck between how quickly you need to get at your backed up data, and how resilient you want your solution to be. For example on one end you could merely have your data backed up to a drive attached to the source machine. This would give you the fastest access to it, but at the cost of a single point of failure. On the other end of the spectrum you can have the data backed up to offsite location(s). This would give you the most protection as any harm to your office is far from your data, but also increases the amount of time required for access. Ultimately you either want to have some form of both, a solution that is highly portable (physically moving storage and compatible with your equipment) or even better has all of the above.

Portability
Perhaps one of the more overlooked factors is how portable your backup solution is physically. This becomes a point of particular importance when you have backups that are at an offsite location. For most organizations that aren't in the 'large' category it is unlikely that you'll have a fiber link running across to your offsite location. So if/when an emergency strikes your main office you need to be able to physically move the data and then make use of local link speeds. Remember this when choosing your solution as the ability to do this can vary greatly depending on what sort of hardware requirements are involved, and the manner in which the software operates.

Administrative Cost
One of the banes of the small IT shop is the near impossibility of its associates to truly specialize. The needs of the business, and likely size of available staff tend to demand that the technician/administrator/engineer in this role be a generalist. It's important to keep this mind when picking your backup solution, as it would be a terrible situation to need to conduct a restore, but have no experts in its use to conduct it. If the product requires a significant amount of additional training to operate it can end up costing the business significant resources. The cost is incurred doubly so if the training itself isn't of a certain caliber as well. The long and short is that 'simple' and 'intuitive' should be your watch words here.

Security
The manner in which your data is stored and transmitted is obviously important. Looking around you are likely to find that most if not all of the notable solutions out there at the very least transmit data in an encrypted manner between target and source. The differentiator here is going to be the manner in which its stored after the job is complete. Do you have the option to encrypt the data? If you use third party encryption does it effect their storage format? Checking this functionality is especially important for those of you in the medical field who have to comply with HIPAA (The Health Insurance Portability and Accountability Act). Also consider the discrimination of data here. For example if I log onto one target machine am I capable of pulling data down to it that belongs to another? While it may sound convienent if the answer is yet, it does create a bit of a security vulnerability if one of your target machines were compromised. If your business in a field with confidential data you certainly want to make sure that you have the ability to discriminate and control which clients can access which data.

Truth be told an entire article could be written about each of these factors. These basic thoughts act as an effective guide in researching backup solutions and implementing them into your infrastructure. If anyone would like to discuss the topic in greater detail with me, feel free to comment or shoot me an email: koch.ryan@gmail.com.

Monday, August 6, 2012

Backup Essentials Part Two

For part two of this series we will begin the planning phase. In this phase we'll take an inventory, categorize our data, decide backup types, figure out our backup window, and figure out storage requirements. For this example we will use a small test environment representing the size of a 10 employee company as mentioned in the introduction.

First we'll knock out the inventory. The test infrastructure has a mix of desktops, servers, and remote laptops. I've gone ahead and included a list of these below:

6 desktops of a similar configuration (general user machines)
1 SQL Server (HR)
1 Exchange Server
1 Web server
1 Domain Controller
3 Remote laptops

Having this list we will now need to set priorities. To do this we need to break down an analyze what this business would need to operate, and what it has that merely makes it operate better/more efficiently. While simple, the prioritization below will help us in making decisions on backup types as well as scheduling and storage.

Need to operate:
Domain Controller
Exchange Server
SQL Server
Web Server

Makes business more effective:
Desktops
Remote laptops

Next we need to discuss what backup types are available to us. In general the various backup solutions will give you the ability to do file level backups, service/application backups, and image level backups. In general the decision of which level to use with which machine depends on what expectation of recovery time you have, the location of the machines, and what the machine is being used for. In our case the desktops, and the remote laptops will require a file level backup. The servers will all require an image level backup, a file level backup, and a service level backup.

After deciding what backup types we're using we also need to decide how this fits into our disaster recovery strategy. Do we need any of this data to be backed up to an offsite location? In our scenario it seems clear that the SQL Server,Exchange Server, Domain Controller, and Web Server all need to be backed up to a remote location. These services should be able to be brought backup at a remote office or home office in the event that the main office is brought down by a disaster of some sort for any extended period of time.

The last two factors to consider are scheduling and storage. For scheduling you have to figure out what your organization's 'production' hours are. This will allow you to create a backup window that will exist to minimize the impact your backup jobs have on the ability of  users to operate. For example if the office is open from 8am-5pm then an effective backup window might be from 7pm-6am. This will give a 2 hour buffer both on the beginning and ending side of the window in case someone stays late, or a backup job runs too long. A lot of the decision is going to be unique to your organization and its needs. Storage is also going to be a bit unique as the requirements are going to be different from backup solution to backup solution. Depending on if you choose to go with an appliance, or software you may or may not have to purchase your own hardware. To fully implement a backup and recovery policy however you are going to want to arrange for some sort of storage system on site at your office, as well as another one at some off site location be it an off site data center, or even someone's home office.

That about covers are basic planning stage. The next article will cover what we need to consider in order to pick and implement a solution. There may even be pictures in that one (screenshots).

Friday, July 20, 2012

Backup Essentials: A 4 part series

As many of you aware one of the topics I fancy writing about is backup and recovery. To appease that desire I've decided to write a 4 part set on what's involved in planning, picking and implementing a backup solution. While you've seen this talked about over and over again, we're at it here because it is truly important. Data loss and downtime is the same as tossing cash out the window, and most businesses can't afford it. Besides let's face it, now matter how well your infrastructure runs, Moore's law will eventually strike and it's best to be prepared.

The series starts with this introduction, an outline of what we'll be trying to accomplish. For our walk-through we will use the example of a company made up of 10 employees. Our goal will be to come up with a backup strategy to propose to this 'company', once they've accepted begin implementation, and then finish off by conducting some testing and concluding on its effectiveness. Our scenario will also involve two separate customer sites, and with machines ranging from standard Windows 7 desktops to an Exchange server and a SQL server.

Check back for the next part where we begin the planning phase. In the mean time I need to finish building up the test environment to use as screenshot materials. This should an interesting set of articles and hopefully will help some of you out there in the course of your careers.

Thursday, July 5, 2012

Users and Security

I do apologize for the delay in getting a new article out. Between the power outages here in Columbus last week and the catch up work that followed the plate has been rather full. Today I started giving some thought to security, and specifically how the actions of Users can effect your policies and planning. It seems that no matter how much care and caution one puts into a great security set up, there is always one weakness to root out and that is User behavior. These beings seem to be able to defeat the greatest of security infrastructure practices and are somehow able to throw a wrench in the most finely configured of ecosystems. And so here is a bit of an overview of some thoughts on how to manage user behavior.

But how to do you prevent the user from accidentally breaching your security? It's not so much a question of control, as it is a question of influence and education. Ultimately the majority of user mistakes are due to a lack of instruction, or knowledge of good practices. It's understandable, most of these users be they internal or external customers have other things to do and have other concerns that have been given a greater priority. As the IT Engineer/Analyst/Manager it ends up falling to you to be the one that breaks this shell, and instructs them on what to do. The importance of taking the time to do this is only going to grow over time, especially since these users are now even bringing in their own devices and conducting business on them. You now not only have the possibility of company infrastructure being mucked up, but also of corporate data leaking through external devices.

How do you accomplish an educational role? It's about the soft skills here. You need to schmooze a bit with other departments and employees in order to gain their trust and cooperation. The idea of IT education needs to be sold as a value added piece, something that will ultimately save the company time and money. I find that his process is very similar to that of starting a new workout program or lifestyle change. It's best to start off just getting the first session/meeting/etc and then the next one. Once you can get a routine going the ride is much smoother, and you've accomplished an institutional change. An example of this might be to send out a weekly email newsletter and partner that with a monthly 'class'. Once you get solid practices in your users' minds you'll start to see improvements in their behavior and perhaps less security oriented incidents.

Outside of purely IT type education, you also need to make sure that policies are clear and published in as many places as humanly possible. In crafting your policies I would suggest taking heed of the manner in which intelligence agencies operate. Users should only have access to infrastructure pieces they have both 'clearance' for and a 'need to access'. This is very similar to the 'clearance' and 'need to know' principal of intelligence that is used to keep information leak to a minimum. Documentation for this principal is critical as the rest of your organization needs to understand the structure for how access is granted, as well as procedures to gain clearance when needed. Along with policies on access a proper acceptable use policy is recommended. The document should detail exactly what behaviors are frowned upon, and what behaviors are considered acceptable practice.

Lastly, and perhaps the most important piece of this is user involvement. If you want to maintain a credible IT department you need to make the users feel involved and keep them in the loop. Regular and predictable communication with as much of your organization as possible will create an environment in which users don't see the IT department as just some strange offshoot of the company that just tells them they can't do things with their system. By creating these venues of communication you'll be able to create a situation where you users aren't following described practices because you said so, but because you convinced them that they *want* to. This type of shift can only lower risk to both your data and your infrastructure.

Thursday, June 28, 2012

Backup 101

I swear I'll post something with some substance tomorrow, but today I wanted to promote the recording of the Backup 101 web seminar I hosted today. My presentation covered an overview of backup essentials that are required for any effective IT knowledge set. I hope to do more sessions like this on a range of topics as time moves forward. If you guys have any requests please feel free to drop me a line.